
December 2017. DeepMind’s team publishes a research paper with ten annotated games in the appendix. They attract intense attention in the chess community.
It is not simply one program beating another. The games invite attention to how it wins.
AlphaZero’s architecture
Understanding the change requires looking at what AlphaZero does and does not do.
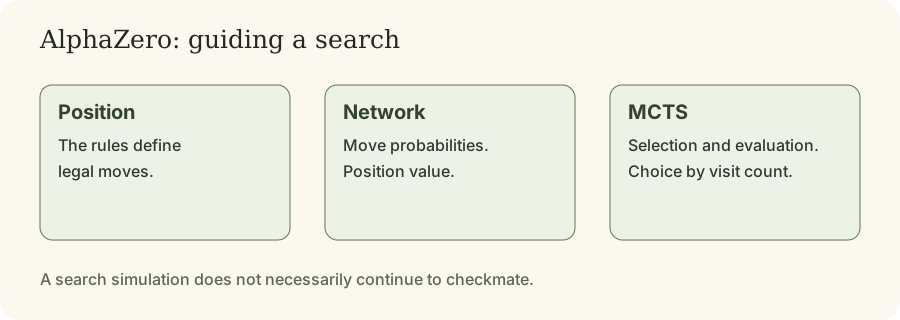
AlphaZero is a deep reinforcement learning system. It combines two technologies:
A deep neural network takes the board position as input and produces two outputs: a probability distribution over legal moves, the “policy head”, indicating promising moves, and a value between −1 and +1 estimating the outcome from the side-to-move perspective, the “value head”.
Monte Carlo tree search, MCTS, uses the network to guide search. Instead of exhaustively traversing the game tree using alpha-beta pruning, MCTS selects paths to leaves of the explored tree; the network supplies evaluations there which are backed up towards the root. These simulations are not all played through to checkmate.
AlphaZero received the game’s rules, without human games, a hand-written positional evaluation or endgame tablebases. This still involved a representation, architecture and training procedure designed by researchers; it was not the absence of engineering choices.
It played 44 million games against itself over about nine hours, adjusting network weights during training. The time needs context: in the 2018 protocol, 5,000 first-generation TPUs generated games and sixteen second-generation TPUs trained the network; the 2017 preprint used 64 for training. This was not one computer in a garage. The learned policy and evaluation were not manually specified as a conventional collection of chess concepts.
The match: 28–0–72
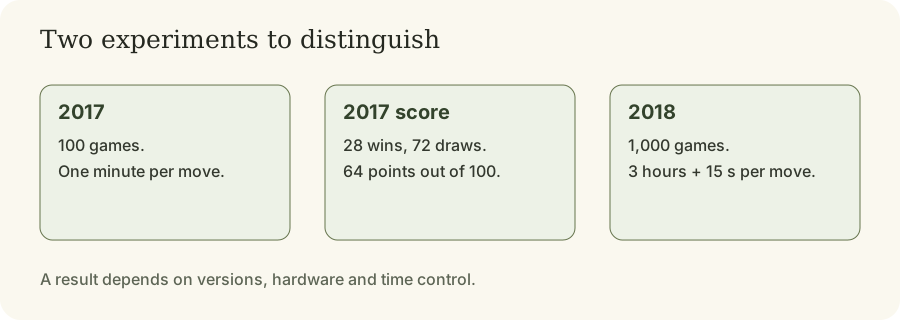
In the December 2017 match, AlphaZero played 100 games against Stockfish 8. AlphaZero scored 28 wins, 72 draws and no losses. With White, it won 25 and drew 25; with Black, it won three and drew 47.
The time control matters: it was not a conventional classical time control. Each program had a fixed minute per move. Stockfish could not allocate its time freely, spend more on critical moves or use its normal time-management strategy. That changes how the result should be read.
The undefeated score was striking, and published wins included clear positional themes rather than only technical endgames. That observation concerns the supplied games; it does not establish a universal style or perfect play.
Legitimate protocol questions include:
- Stockfish ran without endgame tablebases or an opening book.
- Its hash allocation was limited to 1 GB, small for 64 threads.
- One minute per move prevented normal time allocation.
- AlphaZero’s TPU hardware is not directly comparable with Stockfish’s CPUs.
DeepMind subsequently published a revised, peer-reviewed version in Science in December 2018, with a different evaluation: 1,000 games, three hours per game plus fifteen seconds per move, 44 cores for Stockfish, and the Stockfish version that won TCEC 2016.
The result again favoured AlphaZero, with a narrower gap: 155 wins, six losses and 839 draws in 1,000 games, about 57.5% of the score. This differs from the unbeaten 2017 match. AlphaZero also beat Stockfish from each of twelve popular human openings under the experiment’s conditions; time-handicap tests should be distinguished from that result.
Search-speed figures also differ between papers: 80,000 positions per second versus 70 million in 2017, and 60,000 versus 60 million in 2018. Both are roughly a 1:1,000 ratio, but a searched node has different costs and roles in the two systems.
Examining the published games
The supplied games let you study sacrifices, piece activity and pressure on the king. To understand a choice, examine the position and available defences rather than attributing human confidence or intuition to the program.
An evaluation near zero does not prove an engine ignores all initiative: it depends on version, depth and available resources. One example does not measure a universal style.
What AlphaZero rediscovered in opening theory
The opening choices emerging from self-play are another important part of the publications, separate from the match result itself.
Distinguish learning opening sequences from influencing human fashions. The results do not demonstrate that AlphaZero made the London System or King’s Gambit fashionable again. Its illustrated White repertoire centres on 1.d4, 1.Nf3 and 1.c4. The King’s Gambit begins 1.e4 e5 2.f4, a different family. Claims about a human opening’s popularity require separate evidence. The London is a White development system, not a defence.
Several more precise findings are documented:
AlphaZero developed human opening choices through self-play. The Science paper’s curves show opening frequencies over training. Without seeing human games, it reached openings generations of players had found and progressively narrowed its repertoire. It tried and abandoned some popular human openings.
A test from twelve prescribed openings. To examine strength beyond a narrow preferred repertoire, the 2018 authors imposed twelve popular human openings with both colours. AlphaZero beat Stockfish from each in those tests.
Positional sacrifices and piece activity. The published games offer examples of giving material for lasting pressure and using kingside pawns for space rather than only as a shield. Such examples are ideas to analyse, not a universal instruction.
Lc0 is a free software project inspired by AlphaZero. That lineage does not guarantee greater instructional value than Stockfish.
Convergence: Stockfish NNUE and the limits of the dichotomy
In September 2020, with version 12, Stockfish integrated NNUE, Efficiently Updatable Neural Network, introduced in shogi by Yu Nasu in 2018 and then adapted to chess.
NNUE replaced the traditional hand-written evaluation with a neural network trained on millions of positions evaluated by Stockfish. It was designed to evaluate quickly on an ordinary CPU, without requiring a graphics card for that task. This combined alpha-beta search with learned positional evaluation.
The team’s tests credited the NNUE change alone with at least 80 Elo under their test conditions, a substantial gain for an already strong engine.
The simple dichotomy “Stockfish means brute force, AlphaZero means deep learning” is therefore inadequate. Neural evaluation and alpha-beta search can be combined. Comparing engines requires specifying version, hardware and time control.
What you can use in your own analysis
An engine game can offer an idea to check: activity versus material, space or king safety. You still need to understand the variations. A successful sacrifice in the published protocol is not general permission to sacrifice in a superficially similar position.
Comparing versions and conditions also encourages caution when reading evaluations. Match strength and explaining a move to a human player are different questions.
Read the scoreboard as a match, then as a set of cases
Try a small calculation with the 2018 figures. Give AlphaZero a full point for each win and half a point for each draw. Its 155 wins and 839 draws yield 574.5 points out of a possible thousand. Now suppose you were to remove all the draws and ask what fraction of the remaining games AlphaZero won. The answer would be much larger. Both calculations use exactly the same games, yet they answer different questions. The first describes a match score under normal chess scoring; the second describes only games in which somebody won. Quoting the latter as the program's ordinary chance of winning would be a substantial mistake. There were 155 outright wins in the full sample.
The same selection problem occurs in a more interesting form when you play through the most memorable games. If an editor gives you five striking wins involving sacrifices, you have an excellent collection for a lesson on compensation. You still have no sample from which to estimate how often the program sacrifices material. For that, define what counts as a sacrifice, inspect wins, draws and losses, record opportunities where the program declined to sacrifice, and keep the version and test conditions fixed. Sacrificing in five of five selected illustrations and sacrificing in five of five genuine opportunities are entirely different observations.
Turn a famous engine move into your own analysis
Take a published game and stop one move before the annotation that interests you. Hide the players' names and the result. Write down the material balance and the squares to which the least active piece could plausibly move. Next give each side one useful move it would like to play if allowed a free turn. If your explanation of a sacrifice is “White gains time”, say whose intended move is delayed and which piece benefits from that delay. You now have something more precise than an impression of attacking style.
Make two versions of your worksheet. On the first, let the defender accept the offered material; on the second, let the defender decline it with a developing or simplifying move. Keep a separate diagram for each branch. A sacrifice whose compensation depends on the opponent capturing immediately is a very different teaching example from one that strengthens the attack either way. When you finally check with an engine, look for the first move where its analysis diverges from your written branch. Do not quietly replace your original defence with the engine's and then claim that the outcome was obvious.
Finish the exercise by changing one feature in a legal test position, perhaps moving a defending piece to cover a flight square. Ask whether your reason for the sacrifice still holds. This final diagram is something you constructed, so keep it separate from the historical game. You can learn a perfectly sound lesson about an open file or an overloaded defender while remaining uncertain about the best move in the original position.
Sources
- Silver, D., et al. (2017). Mastering Chess and Shogi by Self-Play with a General Reinforcement Learning Algorithm. arXiv. Text.
- Silver, D., et al. (2018). A general reinforcement learning algorithm that masters chess, shogi, and Go through self-play. Science, 362, 1140–1144. Article and supplement.
- Stockfish team (2020). Introducing NNUE Evaluation. Announcement.
- Stockfish team (2020). Stockfish 12. Announcement.
- Lc0 project (undated). Leela Chess Zero. Introduction and download.
Comments