There is something striking about expressing strategy in an old game of intuition and art through a short algorithm. Minimax formalises strategic choice in a zero-sum game as a mathematical recurrence. It also provides a useful analogy for organising calculation, without being a demonstrated description of your brain. For the theoretical framework, see game theory in chess; for existence of a game value under specified rules, see Zermelo.
The intuition behind minimax
Imagine playing White and wanting the best move. Define it as the move yielding the best final result when the opponent also chooses optimally.
That recursive definition is minimax’s core. White maximises the outcome from White’s perspective; Black minimises it from that same perspective, equivalently maximising from Black’s. The players alternate at successive tree levels.
A mathematical formulation is:
Here is the current position, remaining depth, $C(p)$ the legal moves and the position after move .
The evaluation function: the engine’s assessment
Minimax would solve a finite chess tree if the complete tree could be explored to terminal positions. That is not practical with current resources because of combinatorial growth. Shannon’s order of magnitude illustrates move-sequence explosion, not an exact leaf count. Search is stopped at finite depth, and nonterminal positions receive a heuristic evaluation.
A traditional evaluation combines material, mobility, king safety and pawn structure. These help interpret a position but are not context-independent absolute values.
Stockfish integrated NNUE neural evaluation in 2020. Distinguish that architecture from older hand-written sums of features. In the recurrence, “evaluation” must return exact utility for a terminal outcome and an estimate for a position cut off only because depth reached zero.
Alpha-beta pruning: avoiding unnecessary work
Unpruned minimax grows rapidly. With depth half-moves and uniform branching , leaf count is on the order of . For and , leaves in that illustrative model.
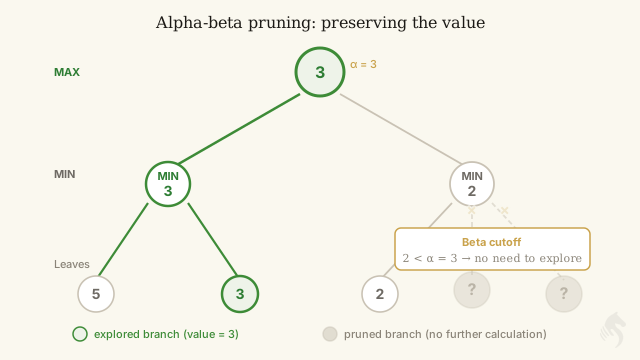
Alpha-beta pruning, associated with work by several researchers including John McCarthy, reduces work by skipping branches that cannot influence the final decision.
If White already has an option guaranteeing value , and a branch lets Black force a value below for White, White need not choose that branch. A better option is already available.
Maintain two bounds in the same score perspective:
- : a lower bound available to the maximising player, White here.
- : an upper bound available through the minimising player, Black here.
When , the current branch can be cut because it cannot change an already available ancestor choice.
With ideal move ordering, cost approaches . This is an asymptotic order, not an equation yielding an exact real-position node count.
Negamax: simplifying the formulation
Negamax uses and evaluates from the side-to-move perspective. The sign changes when the side changes. It reformulates minimax; it does not describe every engine or guarantee a precise reduction in code length.
Null-move pruning: testing a hypothetical pass
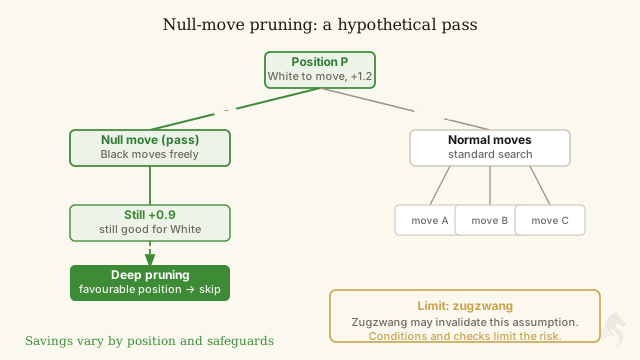
A useful heuristic asks what happens if you pass your turn. If the position remains favourable despite giving the opponent a move, the engine may cut further analysis under specified conditions. This is null-move pruning.
The hypothetical pass is not a legal chess move. Zugzwang is a known risk: having to move can worsen the result, particularly in some endgames. Implementations add conditions and checks to limit that risk. No universal two-to-fourfold speed gain is established here.
Advanced techniques in modern engines
Engines such as Stockfish add techniques beyond basic alpha-beta:
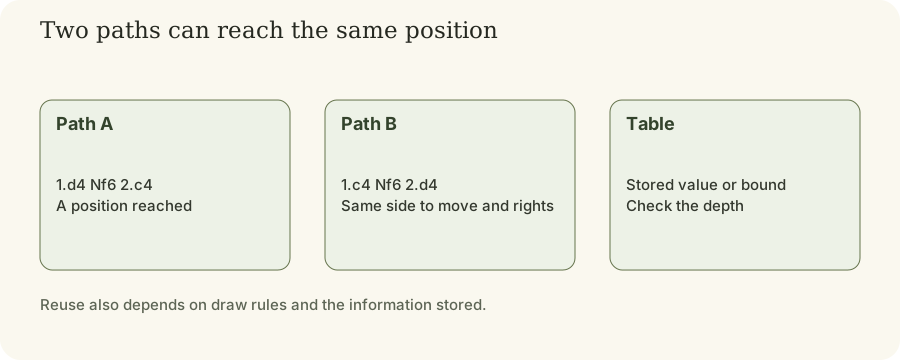
Transposition tables: cache information about previously searched positions. When another move order reaches a matching state, the engine may reuse suitable information instead of repeating all the work. Reuse depends on stored depth, bound type and relevant state.
Iterative deepening: search depths 1, 2, 3 and onward rather than start immediately at . Earlier iterations help order moves for later searches and improve pruning efficiency.
Quiescence search: at the nominal cutoff, continue selected tactical moves according to the implementation rather than always evaluate statically. A checked king requires legal responses, not captures alone. This helps address unresolved tactical sequences that would distort a static score.
Search extensions: some lines receive additional depth, such as those involving checks, advanced passed pawns or other critical conditions, according to the engine’s design.
Late move reductions, LMR: less promising later moves may be searched at reduced depth to save time. A better-than-expected result may trigger further search.
Search that evolves
Stockfish’s published code combines search, transposition tables, iterative deepening and selective mechanisms. Those should not be confused with exact alpha-beta on a fixed tree.
The 2020 NNUE announcement illustrates another change: replacing evaluation without abandoning the alpha-beta search family. A modern engine is not merely a material formula followed by blind exploration.
AlphaZero and alternatives to classical minimax search
In 2017, DeepMind published AlphaZero results: learned self-play evaluation and search beat Stockfish in a particular experimental setup. Training hours need the accompanying hardware and protocol context.
AlphaZero uses neural-network-guided Monte Carlo tree search, MCTS, rather than the conventional minimax search described above. Search selects paths using its learned policy and evaluates explored leaves with the network; simulations do not all run to checkmate.
Published games attracted attention through long-term material sacrifices and piece activity. Calling the style intuitive or creative describes an interpretation of moves, not a measured human cognitive process in the program.
AlphaZero demonstrates that conventional alpha-beta is not the only route to strong chess performance. It does not establish a “deeper human understanding” or solve the game. For the combinatorial problem, see why chess is an almost impossible mathematical problem; for another framework requiring careful distinction, see chaos theory in chess.
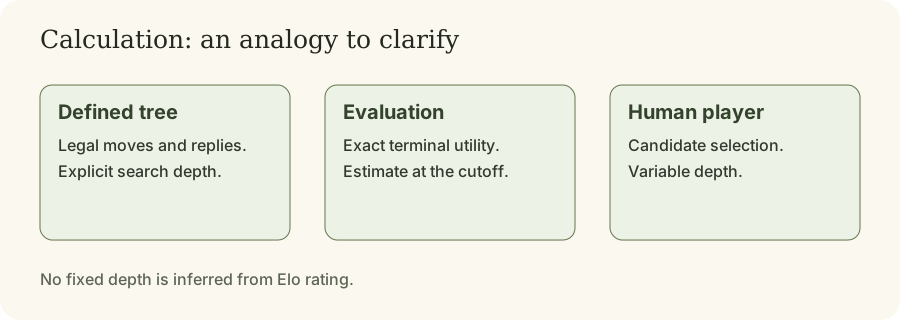
Minimax as a tool for your calculation
When asking “If I play there, what is their best reply?”, minimax can organise your reasoning. That does not show your brain executes it or assign three-to-eight or seven-to-ten levels to a player category.
In a training position, choose two candidates and examine a reply to each. Then look for a defence you had not considered. The goal is better checking, not reproducing a measured human search depth.
Sources
- Russell, S., & Norvig, P. (undated online chapter). Adversarial Search. Artificial Intelligence: A Modern Approach. Chapter.
- Stockfish team (undated). search.cpp. Official repository. Code.
- Stockfish team (2020). Introducing NNUE Evaluation. Announcement.
- Silver, D., et al. (2017). Mastering Chess and Shogi by Self-Play with a General Reinforcement Learning Algorithm. arXiv. Article.
Comments